

By Careerflow Human Data Labs
ResumeBench: the frontier AI benchmark for resume extraction
18 agentic parsers and vLLMs evaluated on 300 curated resumes
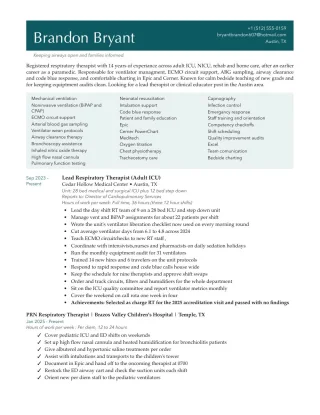
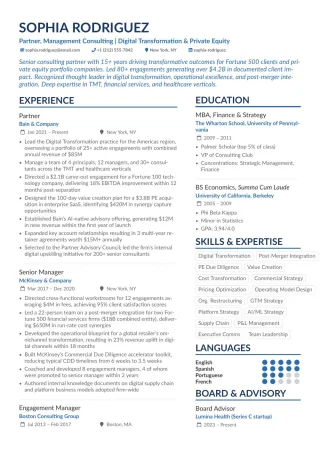
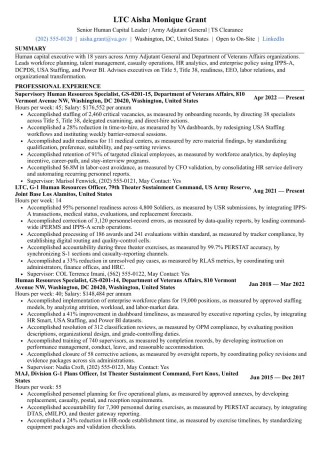
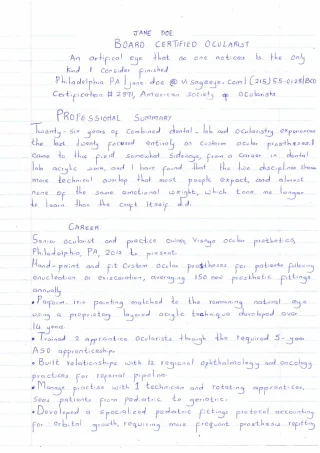
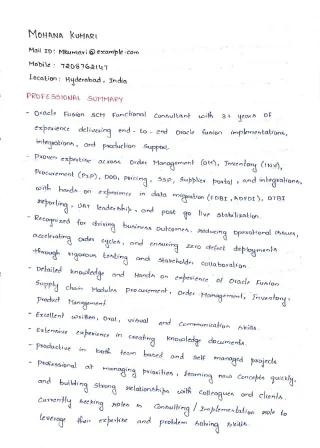
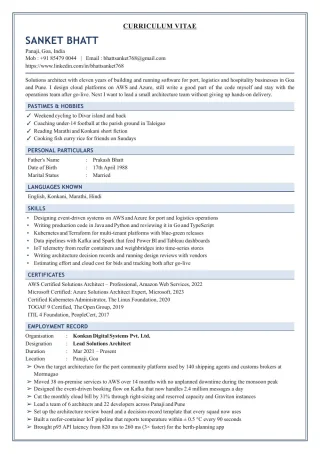
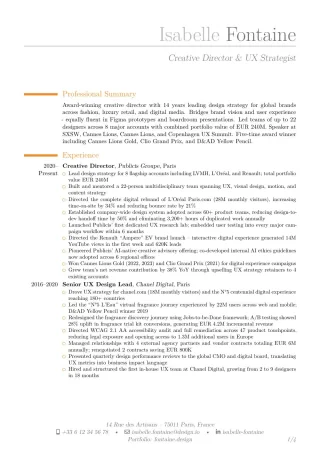
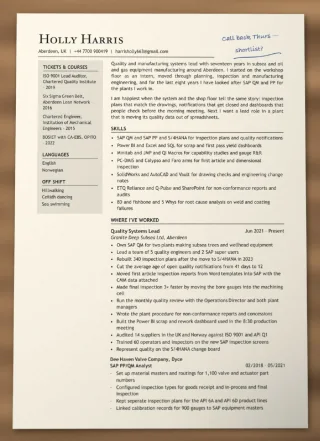
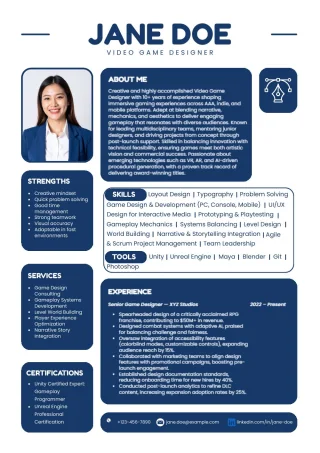
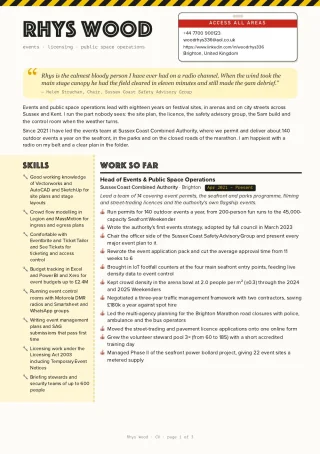
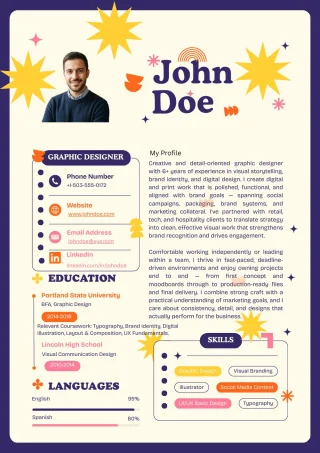
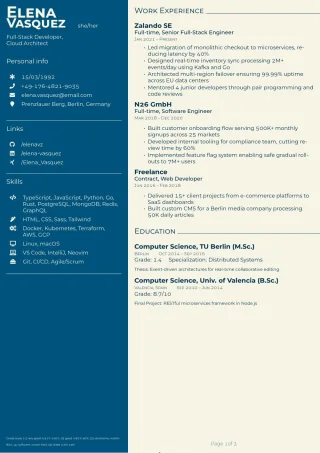
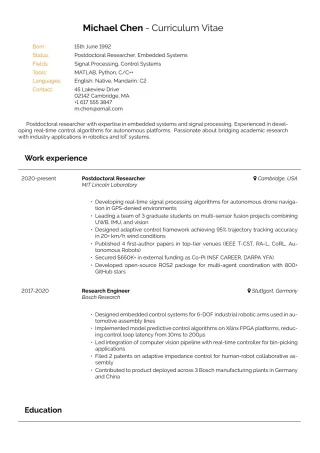
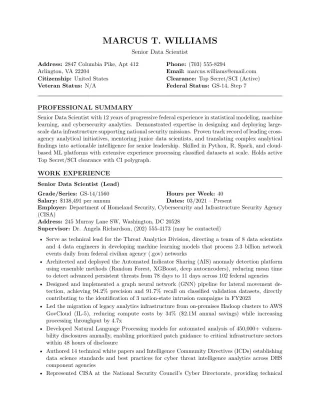
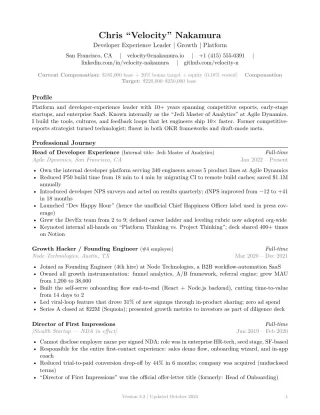
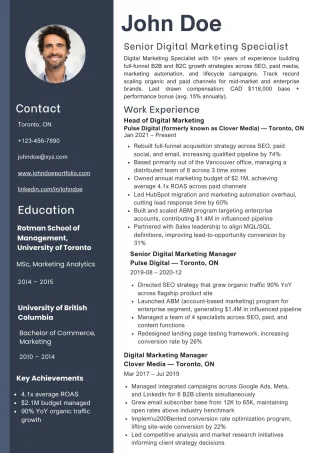
Pages from the benchmark.
Head to head
Pick any two systems and see where they differ.
87.16
LlamaParse Extract Agentic Plus
A · Document API
85.55
Reducto Deep Extract
B · Document API
LlamaParse Extract Agentic Plus is ahead by 1.60 points on these 300 resumes.
Full comparison →- Many entries 83A 85.0 · B 84.3+0.7
- Long bullet lists 101A 84.9 · B 84.5+0.5
- Split across pages 85A 85.3 · B 84.1+1.2
- Big skills list 60A 86.0 · B 85.8+0.3
- Custom sections 105A 85.1 · B 82.6+2.5
- Combined headings 37A 84.6 · B 82.7+1.9
- Promotions 88A 87.4 · B 86.0+1.4
- Partial dates 138A 87.0 · B 85.2+1.8
- Overlapping jobs 69A 84.1 · B 85.9−1.8
- Accented text 13A 92.0 · B 85.5+6.5
Accuracy, cost and speed
How accurate each system is, what it costs, how fast it runs.
- Document API
- Vision LLM
What’s in the benchmark
300 resumes across fields and formats. 20 are public with ground truth; the rest on request.
- resumes
- 300
- pages
- 837
- entries
- –
- bullets
- –
- skills
- –
Every value in the ground truth was checked against the page by hand.
Fields people work in
- Engineering & trades4314%
- Operations & programs3211%
- Data & AI258%
- Software development248%
- Healthcare & science238%
- Marketing, media & design238%
- Finance & accounting217%
- Law & public sector196%
- Cloud, IT & security196%
- Education & other196%
- Tech leadership & product186%
- Consulting, strategy & risk186%
- Sales & customer service165%
Kinds of resume
- Everyday resumes21271%
- Expert-built (Canva / LaTeX)3211%
- Scanned & rotated196%
- Distractor layouts186%
- Resume-builder templates103%
- Handwritten93%
Page layout
- Single column19565%
- Two-column238%
- Two-column sidebar5418%
- Three-column207%
- Table grid83%
Pages per resume
What recurs
- Partial dates138
- Custom sections105
- Long bullet lists101
- Promotions88
- Split across pages85
- Many entries83
- Sidebar or grid82
- Overlapping jobs69
What makes a resume hard
The resume features that cost parsers the most.
- Handwritten · 9 resumes−31.7
- Image only · 28 resumes−10.5
- Custom sections · 105 resumes−4.4
- Busy page · 18 resumes−4.1
- Many entries · 83 resumes−2.9
- Long bullet lists · 101 resumes−2.8
- Overlapping jobs · 69 resumes−2.5
- Split across pages · 85 resumes−2.2
F1 points lost by the median system on resumes with each label. Which parser handles each kind best →
Eight resumes up close
Open one for its pages, its ground truth and every system’s score.
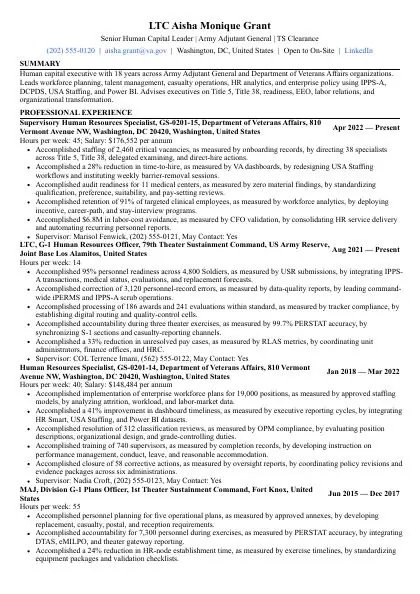 Resume-builder templateSupervisory Human Resources Specialist, GS-0201-15 · 3 pagesQwen 3.8 27B88.5LlamaParse Extract Agentic Plus83.9
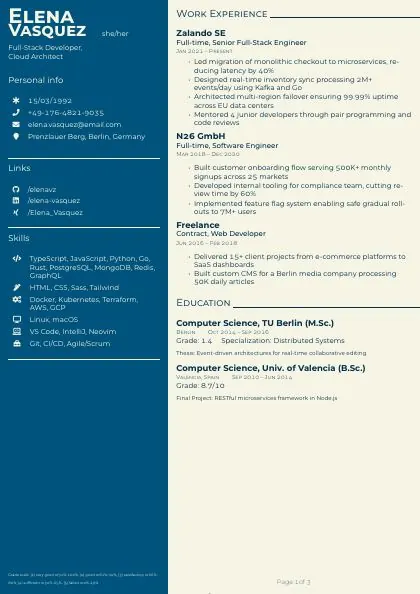 LaTeX CV with a running headerSenior Full-Stack Engineer · 3 pagesClaude Opus 4.878.1Reducto Deep Extract77.7
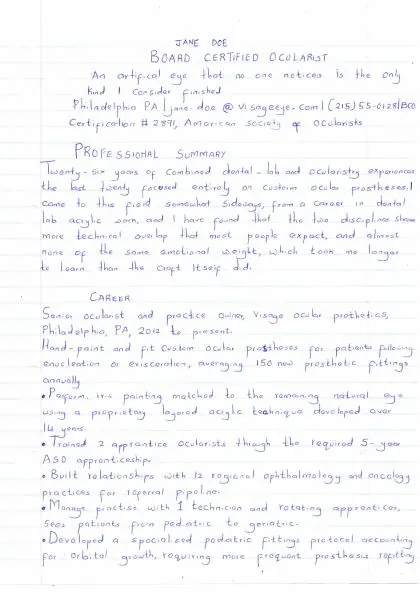 Handwritten resume, six pagesSenior ocularist and practice owner · 6 pagesLlamaParse Extract Agentic Plus74.0LlamaParse Extract Agentic70.4
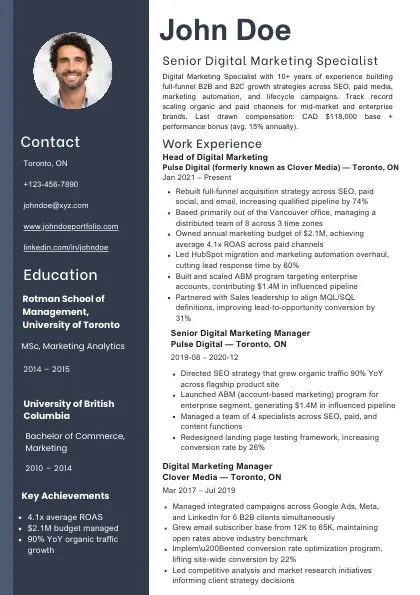 Canva design with a photoHead of Digital Marketing · 2 pagesReducto Deep Extract87.3GPT-5.686.7
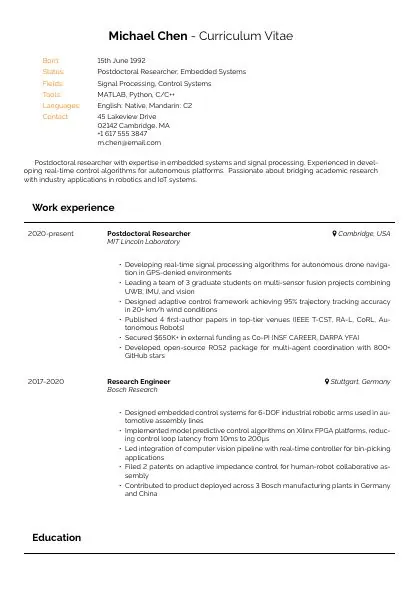 Academic CV, seven pagesPostdoctoral Researcher · 7 pagesQwen 3.8 27B87.0Claude Opus 4.886.2
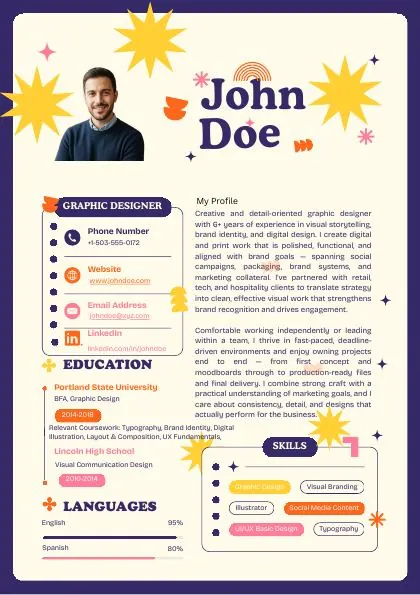 Graphic designer's Canva CVGraphic Designer · 2 pagesQwen 3.5 35B84.4LlamaParse Extract Agentic82.0
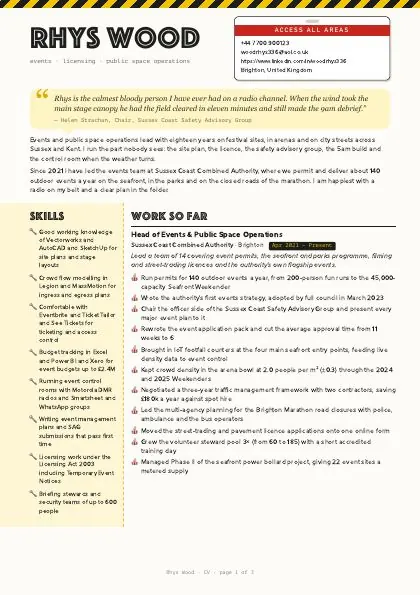 Table grid with emoji bulletsHead of Events & Public Space Operations · 3 pagesGPT-5.599.5LlamaParse Extract Agentic Plus98.4
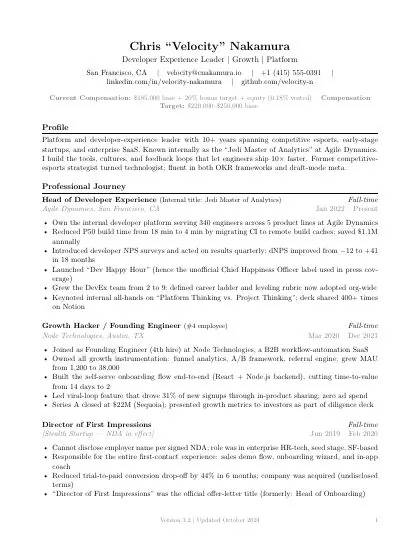 Unusual job titlesHead of Developer Experience (Internal title: Jedi Master of Analytics) · 3 pagesLlamaParse Extract Agentic Plus96.3Qwen 3.8 27B96.3
How a resume is scored
Same PDF, schema and instructions for every system. Each field and bullet is checked word for word. No judge model.
1Normalize
Tidy spaces, dashes and quotes. Case and punctuation still count.
2Align
Match each job to the same job in the truth, by company, title and years.
3Compare
Each field and bullet: 1 if it matches word for word, 0 if not.
4Score
F1 per section, then the average.
A real job entry from the benchmark, as GPT-5.4 Nano read it
3 / 6values right
3 values differ, so this entry scores 3/6.
A resume’s score is the average of its sections. The board averages all 300 resumes.
A missed job lowers recall; an invented one lowers precision. Pick another system to see its answer.
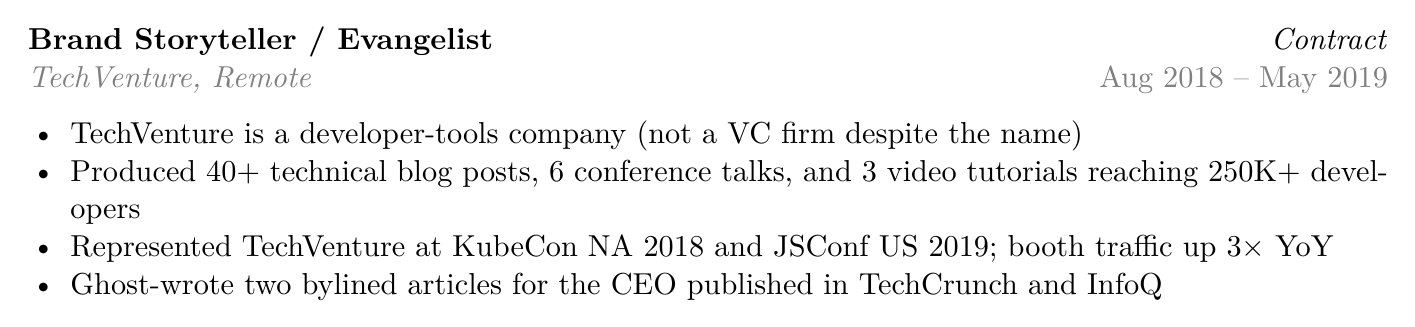
- CompanyTechVenture
- Job titleBrand Storyteller / Evangelist
- Bullet 1TechVenture is a developer-tools company (not a VC firm despite the name)truth: TechVenture is a developer-tools company (not a VC firm despite the name)
- Bullet 2Produced 40+ technical blog posts, 6 conference talks, and 3 video tutorials reaching 250K+ devel- operstruth: Produced 40+ technical blog posts, 6 conference talks, and 3 video tutorials reaching 250K+ developers
- Bullet 3Represented TechVenture at KubeCon NA 2018 and JSConf US 2019; booth traffic up 3× YoYtruth: Represented TechVenture at KubeCon NA 2018 and JSConf US 2019; booth traffic up 3× YoY
- Bullet 4Ghost-wrote two bylined articles for the CEO published in TechCrunch and InfoQ
Every scoring rule 5 definitions
- Precision
- Correct ÷ returned. Drops when a system makes things up.
- Recall
- Correct ÷ expected. Drops when a system misses things.
- Pairing
- Jobs match on company, title and years; schools on institution, degree and years; skills one to one. Order doesn’t matter.
- Empty values
- Empty in both: ignored. Empty in one only: wrong.
- Perfect resumes
- Resumes with nothing wrong and nothing missing.
The schema 14 sections, 150+ fields
| Section | Compared in the F1 | Also under Dates |
|---|---|---|
| basics | name, email, phone, city, state, country, LinkedIn, photo flag, target title | – |
| experience | company, title, city / state / country, remote, role description, URL, every bullet | dates, currently here |
| education | institution, field of study, degree, GPA, location, every bullet | dates, currently studying |
| personalSummary | the summary text | – |
| skills | skill names, de-duplicated, comma-split | – |
| certifications | name, issuer, URL | date |
| customSections | title, summary, every bullet | – |
| awards | title, awarder, summary, URL | date |
| projects | name, URL, company, location, every bullet | dates, in progress |
| volunteering | organisation, role, location, summary, every bullet | dates, currently volunteer |
| publications | title, publisher, summary | date |
| languages · interests · profiles | name / network + URL | – |
Run it on your own parser
Harness, schema, prompt and scorer are open source. Grade your own pipeline or predictions.
careerflow/ResumeBench$ pip install "resume-bench[runners] @ git+https://github.com/careerflow/ResumeBench"
$ hf auth login # the dataset is gated: accept its terms on Hugging Face first
$ resume-bench download
$ resume-bench providers
$ resume-bench run llamaextract_agentic_plus --split test
$ resume-bench grade llamaextract_agentic_plus --split test
$ resume-bench grade-file my_predictions.jsonl --split test


